- Ambiguous lip shapes decoded using surrounding context
- Technology eyed for smart glasses, military robots
Researchers have developed an AI technology that can decode what a person is saying by reading lip movements alone — no audio required — even on loud factory floors or on the battlefield. The technology could eventually be embedded in smart glasses or military robots, enabling communication without voice in environments with extreme noise.
KAIST announced Sunday that a research team led by Professor Noh Yong-man of the School of Electrical Engineering has significantly improved the accuracy of visual speech recognition, a technology that converts lip movements into text without sound.
Visual speech recognition identifies what a person is saying based solely on lip movements. The approach has long faced accuracy limitations, however, because many different words produce similar lip shapes.
Existing AI systems decode sentences word by word from the beginning, meaning a misread early in a sentence can cascade into errors throughout the rest of it.
To overcome these limitations, the research team changed the order in which the AI decodes a sentence. The system now identifies words with clear lip movements first, then uses those as anchors to interpret ambiguous portions based on surrounding context.
The approach resembles solving a puzzle by placing the obvious pieces first and then filling in the gaps around them.
To achieve this, the team employed a diffusion large language model, which iteratively fills in blanks within a sentence. The researchers trained the model in stages — first linking lip movements to text, then predicting sentence length — to improve recognition accuracy.
When decoding an actual sentence, the system estimates multiple possible sentence lengths based on video duration, compares the results and selects the most reliable output.
The team validated the technology's performance using LRS3, a lip-reading video dataset comprising 433 hours of footage. The model achieved a word error rate of 19.4 percent — the lowest recorded among existing technologies trained exclusively on LRS3 as labeled data.
Word error rate measures the proportion of words an AI incorrectly recognizes, omits or inserts compared with actual speech; a lower rate indicates better performance.
The technology is expected to find use in smart glasses that assist people who are deaf or hard of hearing, as well as in noisy industrial settings.
Potential applications in defense are particularly notable. The researchers said the system could serve as a core interface for future military AI — using only a camera to recognize commands from allied forces in battlefields where explosions and machinery make voice transmission difficult, or in situations requiring covert operations.
The team plans to develop a lighter version of the AI model in the form of a small multimodal large language model for deployment on smart glasses and edge robots. The goal is to build an on-device AI capable of reading lip movements and generating subtitles in real time on the device itself, without connecting to a cloud server.
"This research demonstrates that simply controlling the order in which an AI generates words can overcome the fundamental limitations of speech recognition in visually ambiguous conditions," Professor Noh said. "We will lay the groundwork for physical AI that can be trusted and used across a wide range of devices in everyday life and industrial settings."
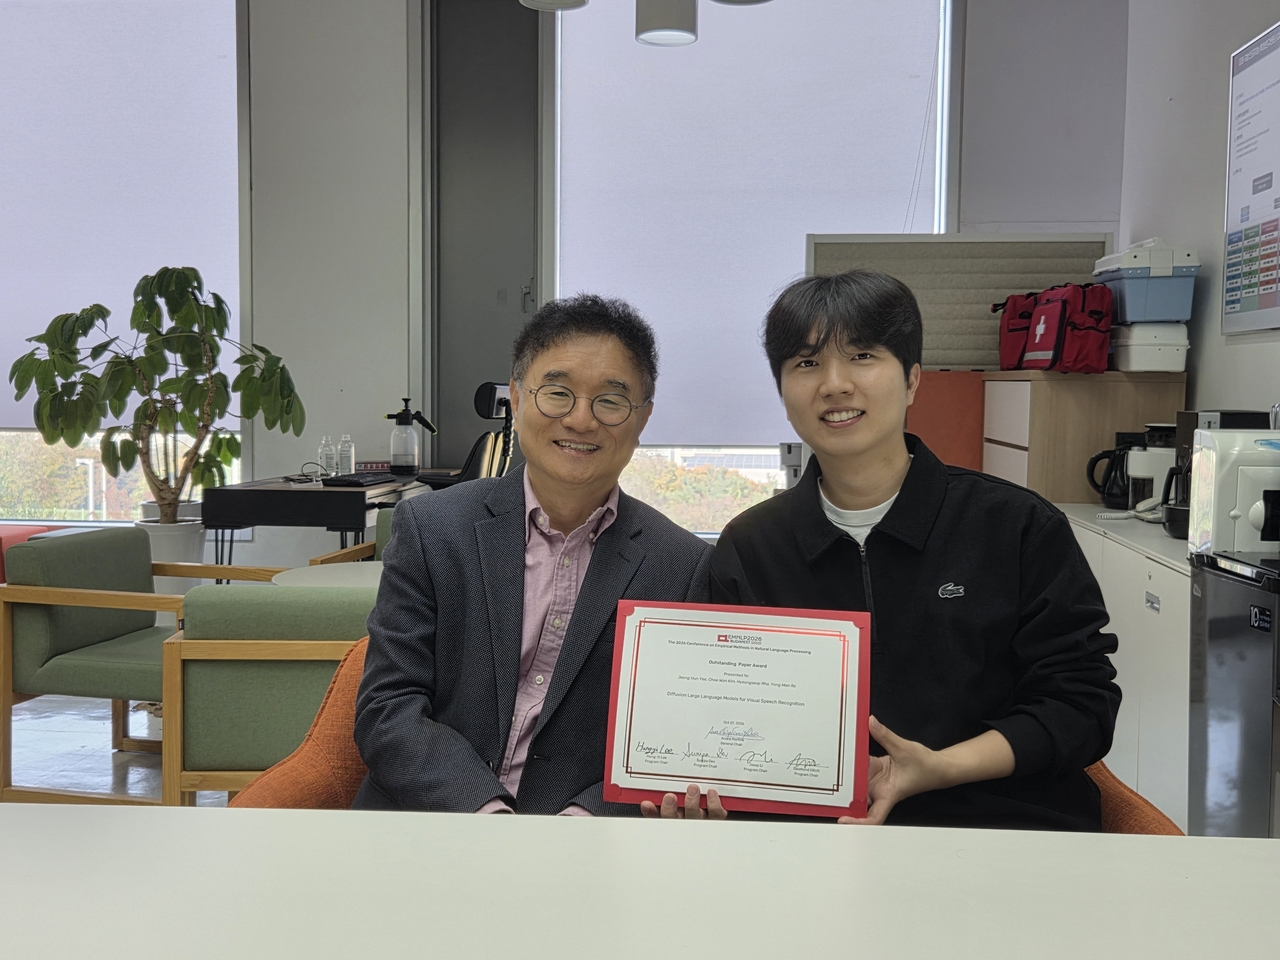
Postdoctoral researcher Yeo Jeong-hun of KAIST served as the first author of the study. The research received an Outstanding Paper Award at EMNLP 2026, an international conference on natural language processing.
nbgkoo@heraldcorp.com